
Joins what you already run
Trivy, Semgrep, Cloud Custodian and Falco findings, plus your AWS and Kubernetes state, in one graph of the environment as it really is. Cloud accounts are read, never written to.

Joins what you already run
Trivy, Semgrep, Cloud Custodian and Falco findings, plus your AWS and Kubernetes state, in one graph of the environment as it really is. Cloud accounts are read, never written to.
Finds the way in
Every route from an internet entry point, through too much privilege, to a sensitive asset - ranked by what to fix first, each with how far its number can be trusted.
Stops it in the pull request
The check goes red only when this change opens a route, names it, and the fix comes back as its own pull request to review and merge.
Says how far to trust it
It grades its own scores against real test outcomes, and says “not enough data yet” rather than make a verdict up.
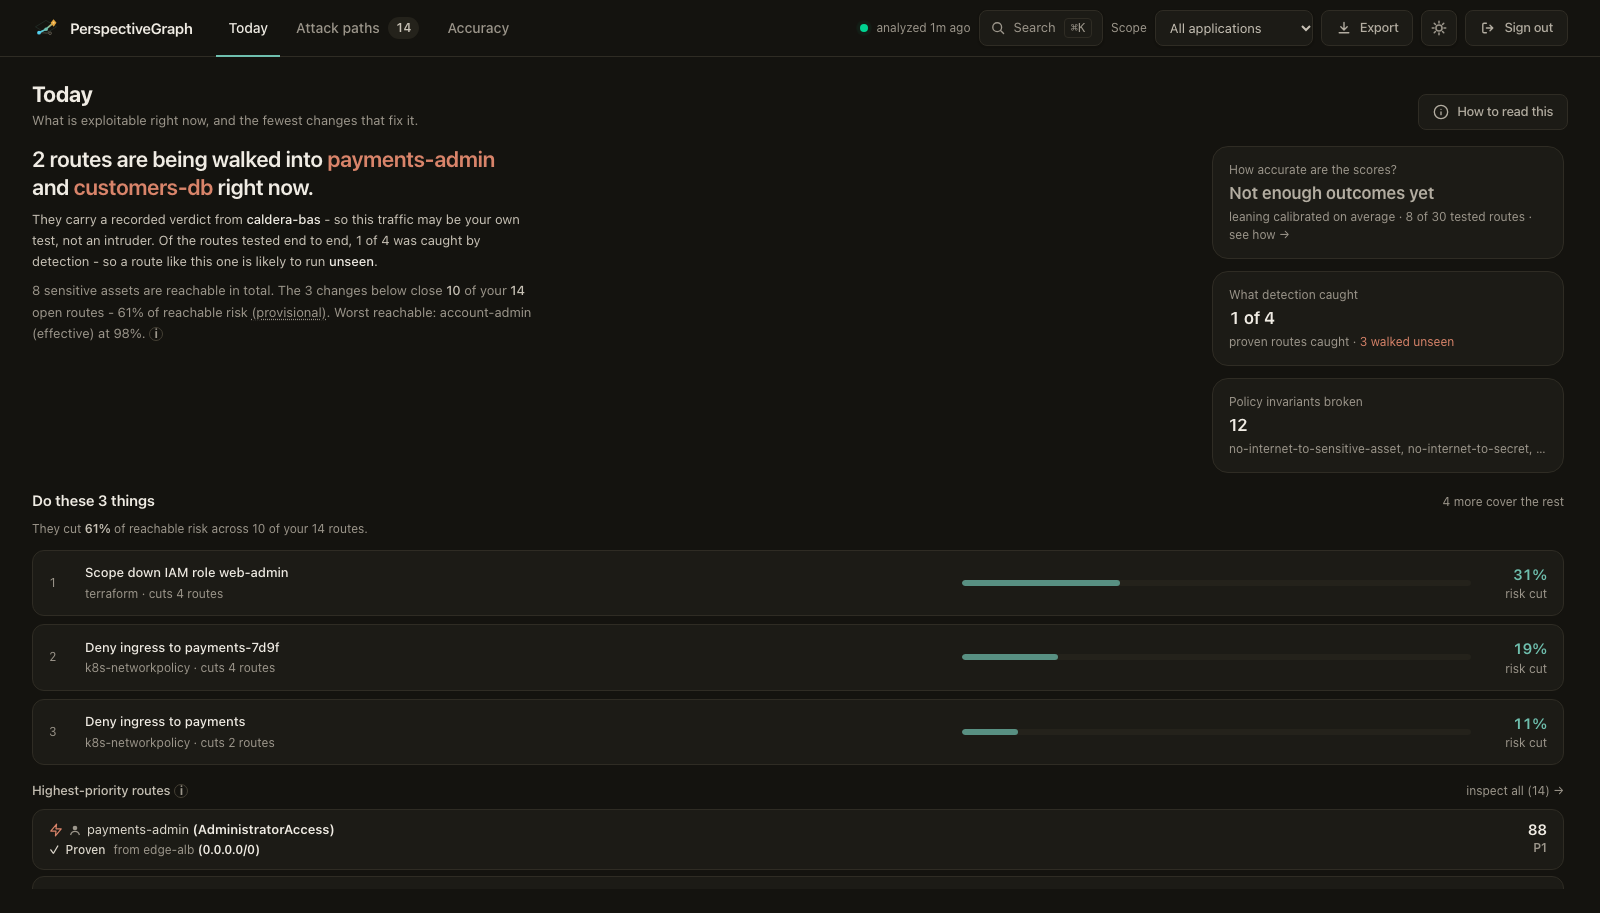
The dashboard on sample scanner output, with synthetic test outcomes recorded so that every panel has something to show - not a real environment. The live demo runs the same sample data with no outcomes at all.
A score is what the model concludes from the evidence it was given, not a measured frequency. Nothing has been calibrated against field data yet, and the engine says so itself - positioning states what is claimed, what is not, and how to check.
Open source under Apache 2.0. It runs on your infrastructure and collects no telemetry. Tried it? Tell us what worked and what didn’t. Contributions, questions and a line in the adopters list are all welcome.